Reserve B300 Capacity

Tell us about your deployment. A solutions architect will be in touch shortly

How many nodes do you need? (1 node = 8 GPUs)

What is your workload?

Timeline

Environment

NVIDIA HGX B200

NVIDIA HGX B200

NVIDIA HGX B200

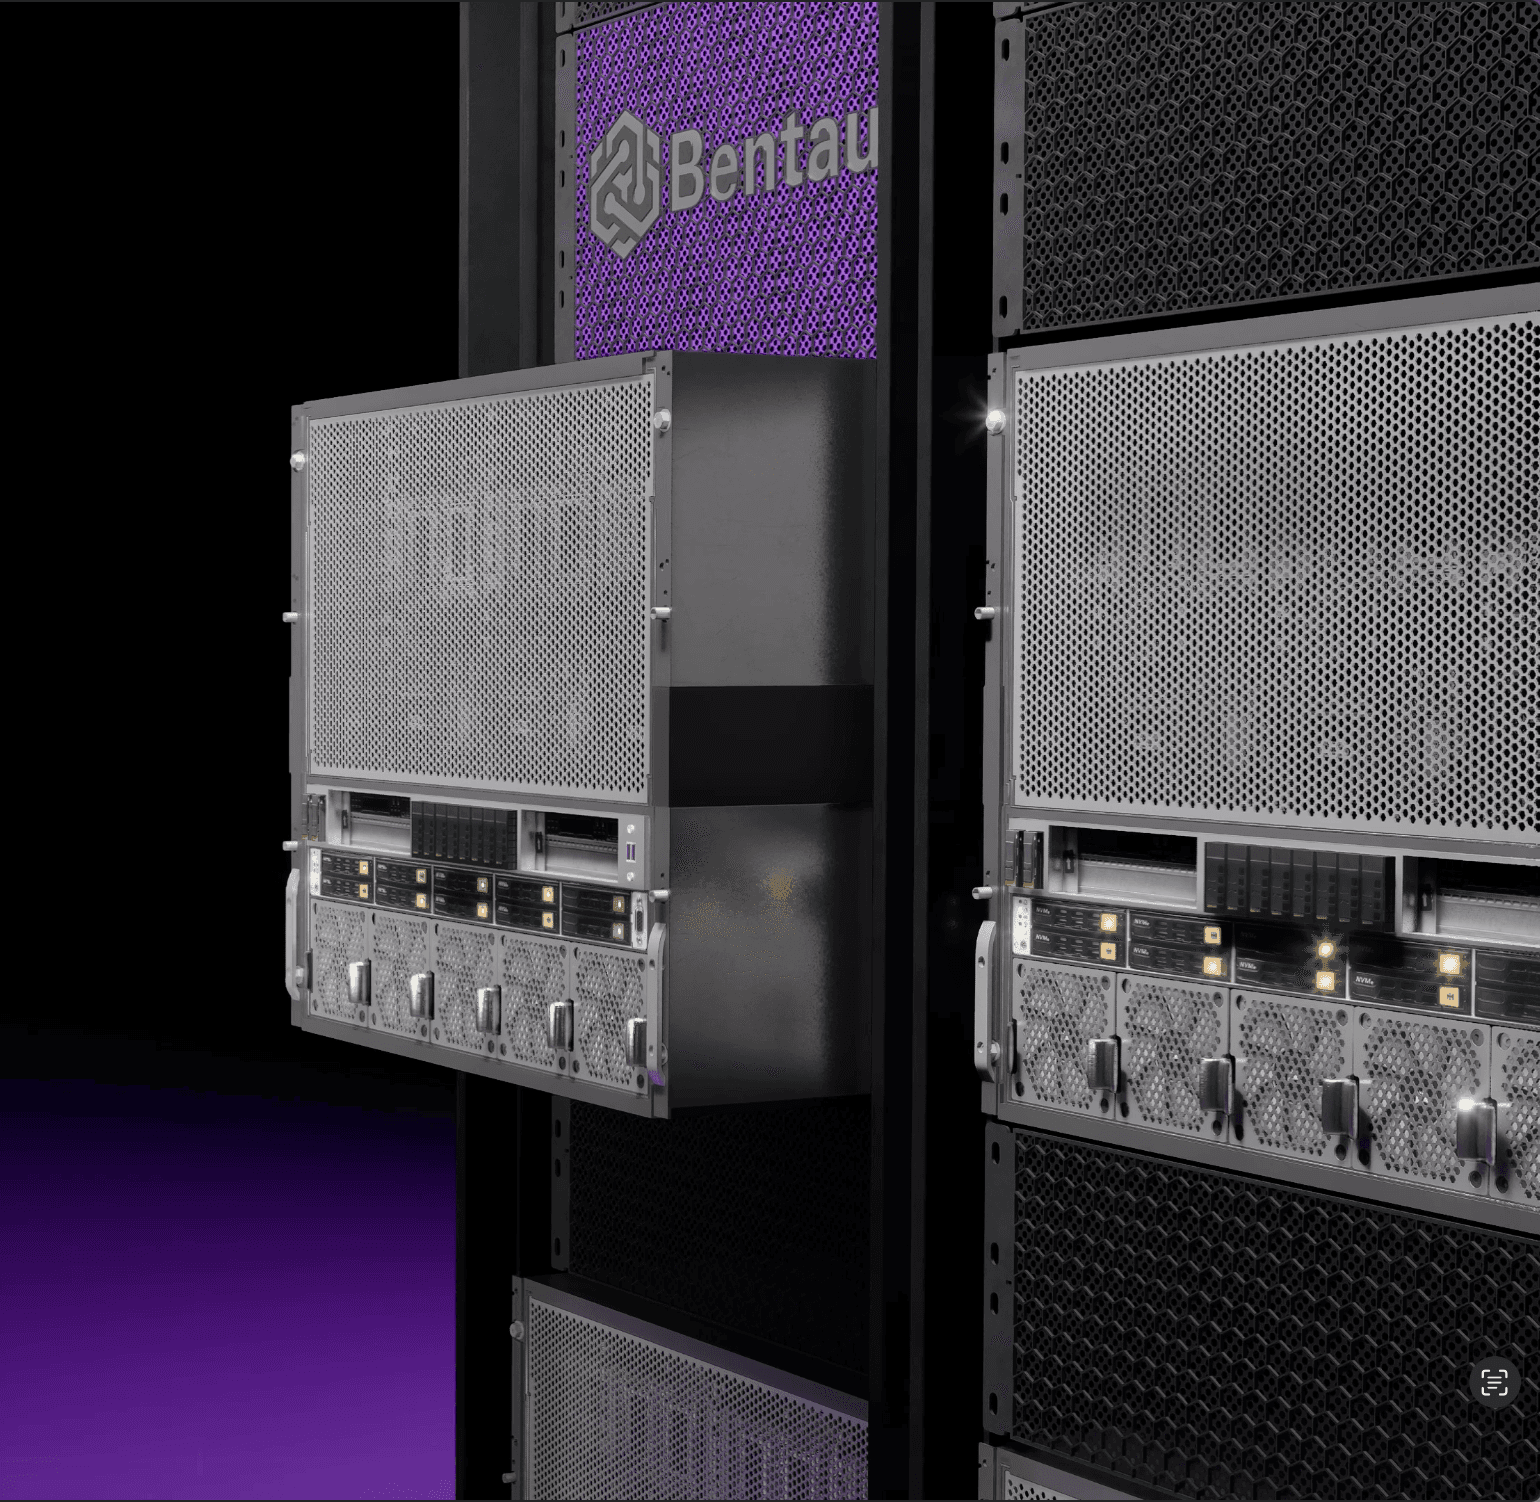
Proven NVIDIA Blackwell performance for training and inference, deployed by Bentaus with short lead times. Reserve capacity now.

Proven NVIDIA Blackwell performance for training and inference, deployed by Bentaus with short lead times. Reserve capacity now.

Proven NVIDIA Blackwell performance for training and inference, deployed by Bentaus with short lead times. Reserve capacity now.

180GB

HBM3E PER GPU

1.8TB/s

NVLink per GPU

1.4TB

Memory per node

8x GPU NODE

NVLink

1.8 TB/s

HBM3E

180 GB

Bentaus is an energy-first NeoCloud that designs, deploys and operates AI infrastructure end to end. Our B200 deployments are engineered for proven performance, efficiency and reliability.

Bentaus is an energy-first NeoCloud that designs, deploys and operates AI infrastructure end to end. Our B200 deployments are engineered for proven performance, efficiency and reliability.

A dark abstract backdrop with soft diagonal ridges, symbolizing secure layers, encrypted data, and a protected connection.
Mobile VPN app

WHY BENTAUS

Why Enterprise Teams Choose Us Over Today's Hyperscalers

Deploy dedicated B200 capacity without the delays, higher cost, or limits of traditional hyperscale solutions.

WHY BENTAUS

Why Enterprise Teams Choose Us Over Today's Hyperscalers

Deploy dedicated B200 capacity without the delays, higher cost, or limits of traditional hyperscale solutions.

WHY BENTAUS

Why Enterprise Teams Choose Us Over Today's Hyperscalers

Deploy dedicated B200 capacity without the delays, higher cost, or limits of traditional hyperscale solutions.

Lower Cost Than Hyperscalers

Enterprise B200 capacity without the hyperscaler premium. Bentaus gives clients transparent pricing and better cost control as GPU demand scales.

Lower Cost Than Hyperscalers

Enterprise B200 capacity without the hyperscaler premium. Bentaus gives clients transparent pricing and better cost control as GPU demand scales.

Proven Blackwell Performance

Powered by NVIDIA Blackwell, B200 delivers native FP4, 180GB of HBM3e per GPU and fast throughput for training, inference and agentic workloads.

Proven Blackwell Performance

Powered by NVIDIA Blackwell, B200 delivers native FP4, 180GB of HBM3e per GPU and fast throughput for training, inference and agentic workloads.

Proven Blackwell Performance

Powered by NVIDIA Blackwell, B200 delivers native FP4, 180GB of HBM3e per GPU and fast throughput for training, inference and agentic workloads.

Short Lead Times

B200 clusters deploy in weeks, not months. Our designs are ready for today's data centers, so your team starts building sooner.

Short Lead Times

B200 clusters deploy in weeks, not months. Our designs are ready for today's data centers, so your team starts building sooner.

Short Lead Times

B200 clusters deploy in weeks, not months. Our designs are ready for today's data centers, so your team starts building sooner.

Super Efficient

Bentaus optimizes B200 deployments for stronger watt-per-token performance, helping clients generate more AI output with less wasted power.

Super Efficient

Bentaus optimizes B200 deployments for stronger watt-per-token performance, helping clients generate more AI output with less wasted power.

Choose Your Pricing Model

On-Demand

Flexible Access

Contact us

/ GPU hour

NVIDIA B200 Blackwell

Ideal for burst inference workloads

Elastic capacity on demand

Managed infrastructure stack

Reserved

Reserved Term ยท Priority Access ยท Locked Rate

Contact us

/GPU hour

Priority access, guaranteed capacity

Lower hourly rate vs. shared cloud

Custom term lengths available

Dedicated solutions architect

AI Factory

Dedicated Cluster


Custom Pricing

Design your own AI factory

Full cluster isolation

Monitoring, support, and SLAs

Additional feature

NVIDIA B200 Specifications

01

GPU Architecture

NVIDIA Blackwell

02

VRAM

180 GB HBM3e

03

Memory Bandwidth

Up to 8 TB/s

04

Tensor Cores

5th Generation

05

FP16 / BF16 Tensor

2.25 PFLOPS dense

06

FP64 Performance

37 TFLOPS

07

FP32 Performance

75 TFLOPS

08

TF32 Tensor Performance

1.1 PFLOPS dense

09

FP8 Tensor Performance

4.5 PFLOPS dense

10

FP4 Tensor Performance

9 PFLOPS dense

11

Network

NVLink 1.8 TB/s

12

Max GPU Power

Up to 1,000W

COMPARISON

HGX B200 vs H200 vs H100

Side-by-side specs per node, so you can pick the right Blackwell or Hopper system for your workload.

Spec (per node)

B200

Top choice

HGX H200

HGX H100

Architecture

Blackwell

Hopper

Hopper

Architecture

Blackwell

Hopper

Hopper

GPUs / node

8ร— B200

8ร— H200

8ร— H100

GPUs / node

8ร— B200

8ร— H200

8ร— H100

Memory / GPU

180GB HBM3e

141GB HBM3e

80GB HBM3

Memory / GPU

180GB HBM3e

141GB HBM3e

80GB HBM3

Total HBM / node

1.4TB HBM3e

1.1TB HBM3e

640GB HBM3

Total HBM / node

1.4TB HBM3e

1.1TB HBM3e

640GB HBM3

FP4 Compute

Yes

No

No

FP4 Compute

Yes

No

No

FP8 Throughput

72 PFLOPS

~32 PFLOPS

16 PFLOPS

FP8 Throughput

72 PFLOPS

~32 PFLOPS

16 PFLOPS

NVLink Fabric

NVLink 5

NVLink 4

NVLink 4

NVLink Fabric

NVLink 5

NVLink 4

NVLink 4

Networking

400G InfiniBand

400G InfiniBand

400G InfiniBand

Networking

400G InfiniBand

400G InfiniBand

400G InfiniBand

Deploy Your B200 Solution Today!

B200 deployments are among the most versatile AI infrastructure solutions moving fast in the market. Our solution architects are ready to help you design, configure, and deploy now.

Available Now

NVIDIA B300s faster than you expected.

Deploy Your B200 Solution Today!

B200 deployments are among the most versatile AI infrastructure solutions moving fast in the market. Our solution architects are ready to help you design, configure, and deploy now.